Typed Diff Questions
I tested whether small, typed questions about a changed hunk gave a useful basis for code review, comparing model agreement while keeping the eventual reviewer separate from the experiment.
Independent research. Corpus sampling, model scoring, calibration and evaluation.
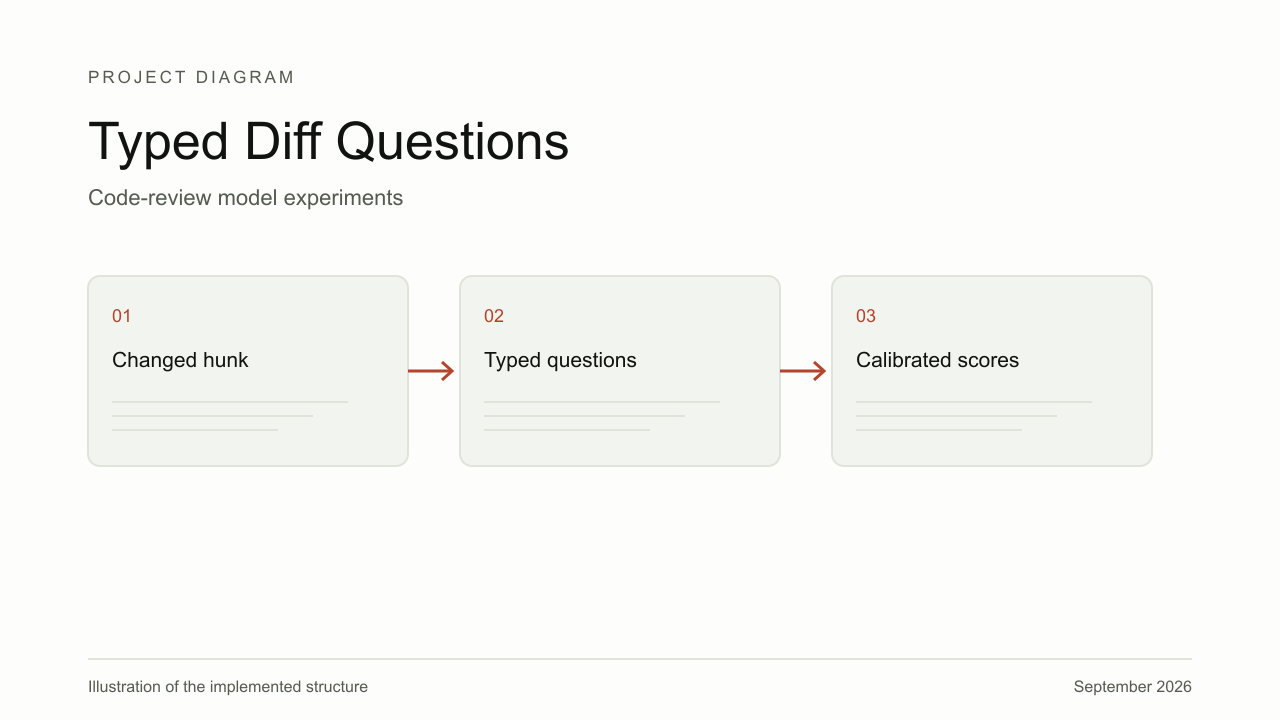
I worked on the question bank before building the reviewer, as a model answering a narrow question about a diff gives something that can be compared across runs without treating the whole review as one judgement, with each question producing a score that could be calibrated and compared with a simple baseline.
The harness sampled code hunks and compared Jev and Haiku with an Opus reference, with repeated scores, class-balanced measures and an always-negative baseline to expose how much the label distribution could inflate apparent agreement.
The findings changed between repositories, and the reference was still another model, so the experiment measured agreement under those conditions without establishing that a developer would accept the findings as real bugs.
The catalogue date follows the first preserved commit on 21 September 2026.
Outcome
Three recorded scoring runs and a reusable experiment harness. Human bug labels and the proposed reviewer interface remain outside the conclusions established by this work.