Personal Language Corpus
This workflow brings transcripts and exports into one small corpus, keeping passage IDs and source information attached to the analysis so a pattern can be checked against the words behind it.
Independent development. Python importers, provenance and analysis workflow.
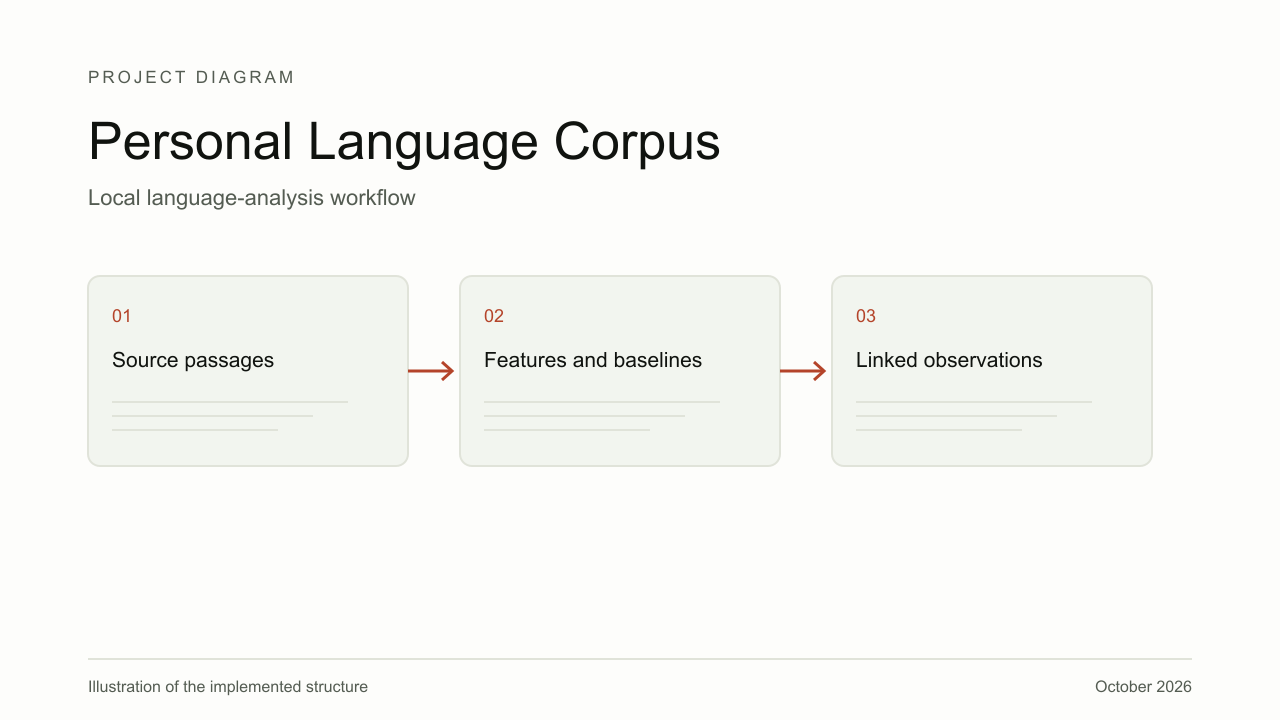
I worked on the structure of the corpus before its interpretation, as a useful observation about language needs a way back to the passage and the source that produced it, with those identifiers kept through the import so later features and observations could still point to the same text.
The importers handle supported transcripts and exports, with stable passage IDs and role information carried into quantitative features, baseline comparisons and the qualitative workflow.
The repository includes sample inputs and workflow tests, which make it possible to try the pipeline without bringing a private conversation history into the demonstration.
The catalogue date follows the first preserved commit on 2 October 2026.
Outcome
A local, testable corpus workflow with provenance and sample data. It keeps the underlying passages inspectable while separating numerical features from qualitative interpretations.