Conversational Timing Lab
I investigated when a speaker has actually finished, keeping turn completion separate from the timing of the next response and testing pause-based assumptions against recorded conversations.
Independent research. Dataset adapters, causal labels, baseline evaluation and audio-model pipeline.
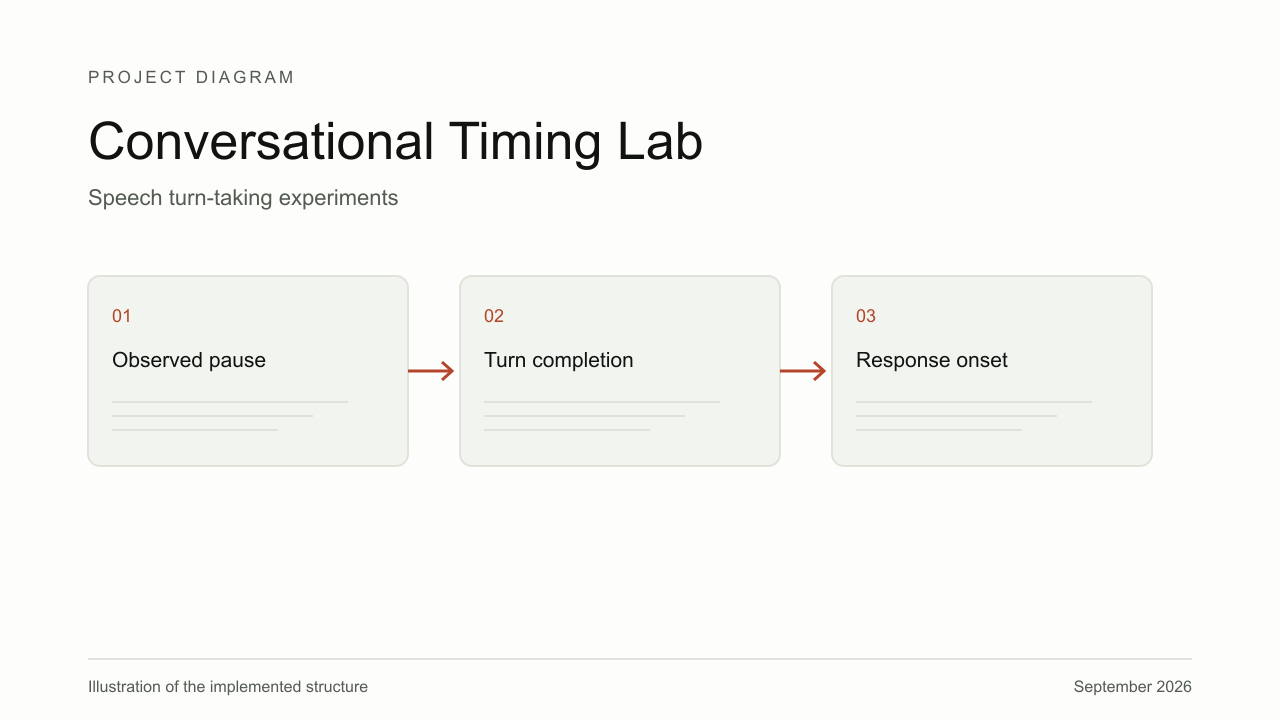
I started with the difference between somebody finishing a thought and somebody pausing inside it, as both can leave the same silence while asking very different things of a voice assistant, with the next speaker supplying the label while the observed silence remained an input available at the time.
The dataset labels came from who spoke next, with observations limited to what was available at that moment, and the baseline evaluation used conversation-level splits to keep meetings from leaking across training and validation.
The recorded baseline run covered 100,004 boundaries from 171 AMI meetings, though the small audio-model run was only an end-to-end pipeline check and did not establish a useful trained predictor.
The catalogue date follows the first preserved commit on 4 September 2026.
Outcome
A reproducible baseline investigation and audio-training pipeline. Pause duration offered limited separation on the recorded meeting data, with the corpus and interruption-budget caveats retained.